Understanding a request does not determine the action
“You charged me twice. I did not use the service last month. I want to cancel.” A reader can identify a billing concern and a cancellation request. But routing the inquiry, checking payment records, deciding whether a refund is allowed, and writing a reply are different jobs. The following scenario illustrates that division; it is not evidence of a deployed Jev system.
Asking a generative LLM to handle everything can mix flexible explanation with business execution in one response. Routing by keywords alone can miss negation and multiple requests. What software needs is a connection between interpreting ambiguous language and invoking established procedures. That makes Jev, the decision model TypeSafe AI announced on September 15, worth examining.
The argument here is not that Jev should replace every if statement. Separating interpretation into probabilistic decisions can make it easier to distinguish the code that enforces rules from the LLM that writes text. A correctly typed answer and permission to act on that answer still require different checks.
Classification without new training is not the whole innovation
Classifiers have long provided this connection. The BERT paper describes adding a classification layer to a text representation and fine-tuning with labeled examples. If categories are stable and enough labeled data exists, a dedicated classifier should remain in the comparison. Jev's arrival does not make established methods redundant.
Classifying text from label descriptions without task-specific training is also an established idea. Yin and colleagues' zero-shot classification research formulates classification across topics, emotions, and situations as a relationship between text and labels. It includes an evaluation setting without task-specific training data. “No additional training required” alone does not identify Jev's distinctive value.
The interesting design is that callers supply questions and candidates and receive decisions ordinary software can consume. When categories change between cases, this could reduce the burden of rebuilding a fixed classifier. It does not remove the need to define candidates or prepare inputs. Adoption should depend on where that work moves, as well as on what work disappears.
Generative LLMs can also return predefined structures
Typed responses are not exclusive to Jev. OpenAI's Structured Outputs constrains generation to a developer-supplied JSON Schema. Its announcement also explains that refusals and incomplete generation need separate handling, and that values inside a valid structure can still be wrong. Structural conformity should not be confused with semantic correctness.
TypeSafe describes Jev as returning bounded decisions in parallel rather than generating text. One potential benefit is reducing the work of parsing a long response afterward. A generative LLM with constrained output can nevertheless provide a similar connection. The comparison should cover whether it completes the same job with the required accuracy, latency, and cost, as well as whether integration is possible.
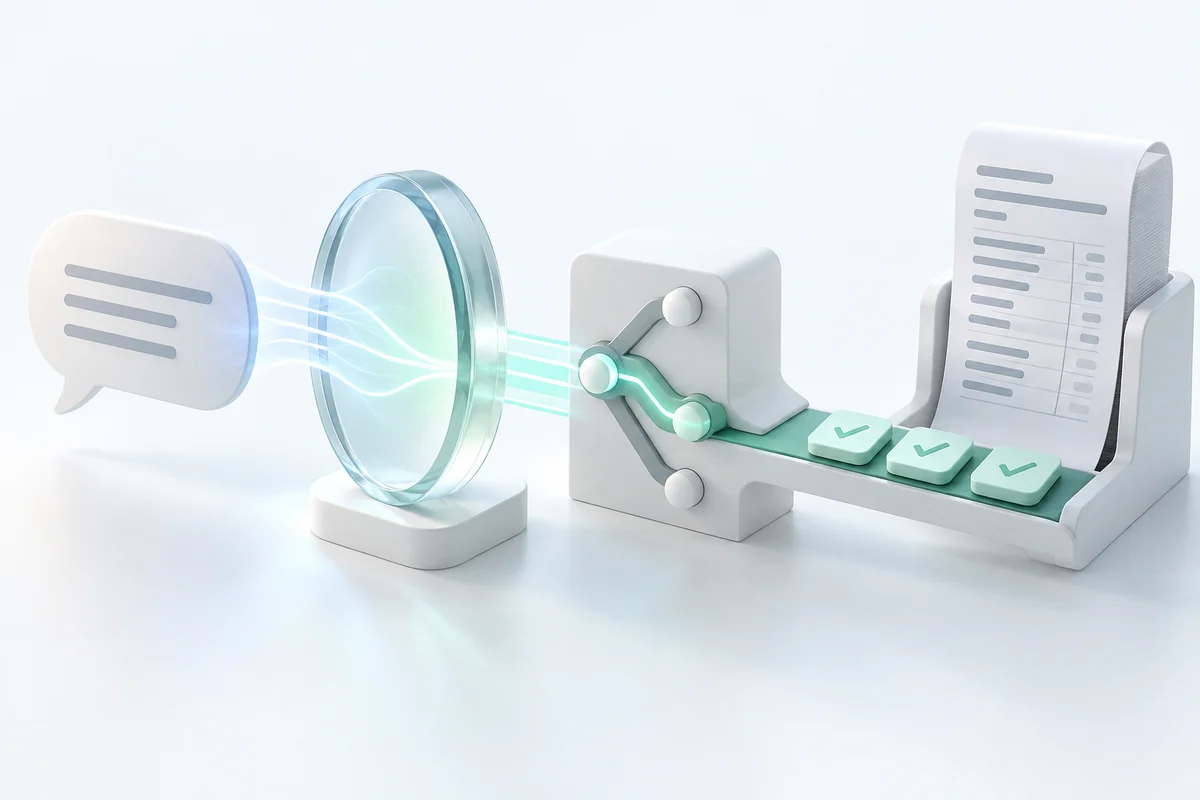
In the opening scenario, Jev could interpret the request, code could check the billing records, and a generative LLM could draft a reply from verified results. Keep text generation where explanation is required, and compare Jev where only a decision is needed. Defining the necessary output comes before selecting one model for the entire process.
The three outputs answer different questions
The published SDK API schema defines Choice, Noul, and Score answers. Each contains numbers, but those numbers serve different purposes. Applying them to the opening inquiry makes the distinction concrete.
Choice: select one candidate
Select the primary issue from “billing,” “technical support,” and “other,” with probabilities for the candidates. If several issues may simultaneously apply, do not force that question into a single Choice.
Noul: assess a proposition
Return the probability that a proposition such as “the customer wants to cancel” is true. A value near 0.5 expresses uncertainty about truth, rather than a medium-strength desire to cancel.
Score: assess ordered levels
Return probabilities across defined, ordered levels such as handling urgency, together with their weighted mean. That mean can fall between levels, so inspect their definitions and distribution before deciding what to do.
The same mean urgency score of 2 could represent probability concentrated on the middle level or split between low and high levels. Those cases call for different investigation. This is an illustration of interpreting the output, not a measured Jev result. A number makes a decision useful only when what it measures is clear.
The question definitions let callers provide instructions and candidate descriptions. Whether “billing” includes cancellation questions, and what distinguishes urgency levels, are decisions for the business. Writing model questions also requires putting previously ambiguous process conditions into words.
Separate probability concentration from observed accuracy
Choice and Score also have confidence values, but reading them as the probability that the whole business process is correct is unsafe. For example, the official comparison LLM adapter implementation computes Choice confidence from concentration relative to a uniform distribution. With three candidate probabilities of 0.8, 0.1, and 0.1, its confidence calculation returns 0.7. This is a worked calculation, not a measurement of Jev's server output.
Calibration as defined by Guo and colleagues, by contrast, concerns the relationship between predicted probabilities and observed accuracy. Among cases predicted at about 0.8, roughly eight in ten should be correct. A score of 0.8 on a single inquiry does not prove that inquiry was classified correctly. Checking calibration also requires enough cases and appropriate ground truth.
Correctly classifying the issue does not establish refund eligibility. Stale billing records, an omitted candidate, or missing execution authority can still cause failure. Recording output probabilities, concentration, and business outcomes separately makes it easier to locate what needs repair when something goes wrong.
Decomposition leaves responsibility for inputs and candidates
TypeSafe's development guide recommends leaving known rules, calculations, exact lookups, and execution in code while isolating semantic interpretation into questions. It also explains that questions in the same call are evaluated independently rather than reading one another's answers. Parallel responses do not eliminate the order in which required checks must happen.
“Does the customer want to cancel?” and “Is the customer unhappy about billing?” can be asked separately about the same text. A condition that requires payment records must wait until those records are retrieved. If an earlier decision changes the next input, code must receive the answer, update the state, and make the next call.
Candidate coverage matters too. Supplying only “billing” and “technical support” cannot enable selection of an absent category. Design an “other” option or an abstention route, and test inputs with missing information. Splitting a task into smaller questions is useful when each question has the evidence it needs and a defined use for its answer.
Connect the decision API to an executable procedure
Returning to the scenario, collect the inquiry and necessary records, then ask Jev about the issue and cancellation request. Code checks the correspondence between the customer and charges, the contract status, and established conditions. Missing information sends the case to review. Once an allowable action is determined, a generative LLM can draft a reply from the result. Recognizing the word “refund” should not itself trigger a refund.
This connection can fail without an incorrect model decision. The SDK call contract distinguishes connection and timeout errors, API failures, and response-validation failures. The application also needs to check that required answers are present, identify the model used, and prevent execution from continuing after a failure.
The division changes human work as well. Reviewing every inquiry is different from examining uncertain cases. Showing the reason for review and the input evidence can help an operator decide; passing over numbers alone may require a fresh investigation. Automation should be measured by the work it removes after checking and correction are included, as well as by API speed.
Read vendor comparisons through their definition of correctness
The Jev announcement describes comparing models within the same workflows, using averaged predictions from strong external models as reference probabilities. This is an interesting comparison of models embedded in fixed procedures. Those references differ from independently established business ground truth, however, so the result is not a success rate for processing real customer inquiries.
The announcement notes potential bias from the capabilities team designing evaluations, favorable short and information-dense demonstration inputs, and speed measurements from the US West Coast. These caveats determine whether results transfer to another environment. Long Japanese inquiries and workflows that retrieve records require their own checks.
The comparison LLM adapter supports both probability outputs and discrete answers. Requesting probabilities is a different latency and cost condition from requesting one issue label. Align necessary outputs, inputs, retries, and connection conditions to avoid either overstating or understating Jev's performance.
Measure automated coverage and errors together
To decide on adoption, collect cases from the actual task. Have people define candidates, correct answers, and missing-information conditions that require review. Use one portion to adjust questions and thresholds, and another for evaluation. Fix the model, question wording, candidates, and input preparation, and separate results for Japanese, English, multiple issues, and unknown issues. Average accuracy alone cannot show where troublesome cases remain.
Selective classification research evaluates a classifier that can abstain through the relationship between errors on accepted cases and the fraction accepted. That perspective is useful for automated processing. It does not transfer the paper's guarantees to Jev; it asks how many of our own cases can proceed and how often those decisions fail.
For example, automatically processing 400 of 1,000 cases with four errors gives 40% coverage and a 1% error rate among accepted cases. Tightening conditions to process 200 cases with one error gives 20% coverage and a 0.5% accepted-case error rate. These are hypothetical values illustrating the comparison. The better option depends on error consequences and the time people spend reviewing the rest. Higher thresholds can still leave confident errors, so inspect their substance as well.
Measure latency including retries and record retrieval, looking at slow cases as well as the average. Include human review, correction, and reprocessing in cost rather than stopping at inference price. Keeping all cases in the denominator, including retrieval failures and missing answers, makes it possible to assess whether adding the decision model improves the whole job.
Define the judgment before removing the if statements
Jev points toward using language interpretation in software decisions separately from text generation. It is most worth comparing where candidates can be defined, handwritten rules struggle with meaning, and uncertain cases have another route. A dedicated classifier for stable categories and a generative LLM for explanations remain alternatives that need evaluation.
In the opening inquiry, the brittle branch worth replacing is one that routes to billing whenever the word “twice” appears. Branches that verify records, enforce established conditions, and check completion of required steps should remain. Making them explicit allows the system to locate and repair problems when interpretation fails.
Adopting a decision API should serve a concrete objective: improve the handling of ambiguous language, preserve visible conditions for people and code to verify, and reduce processing errors and repair work. An answer to that question would make Jev more than another model announcement; it would make it a practical choice for changing how work gets done.