
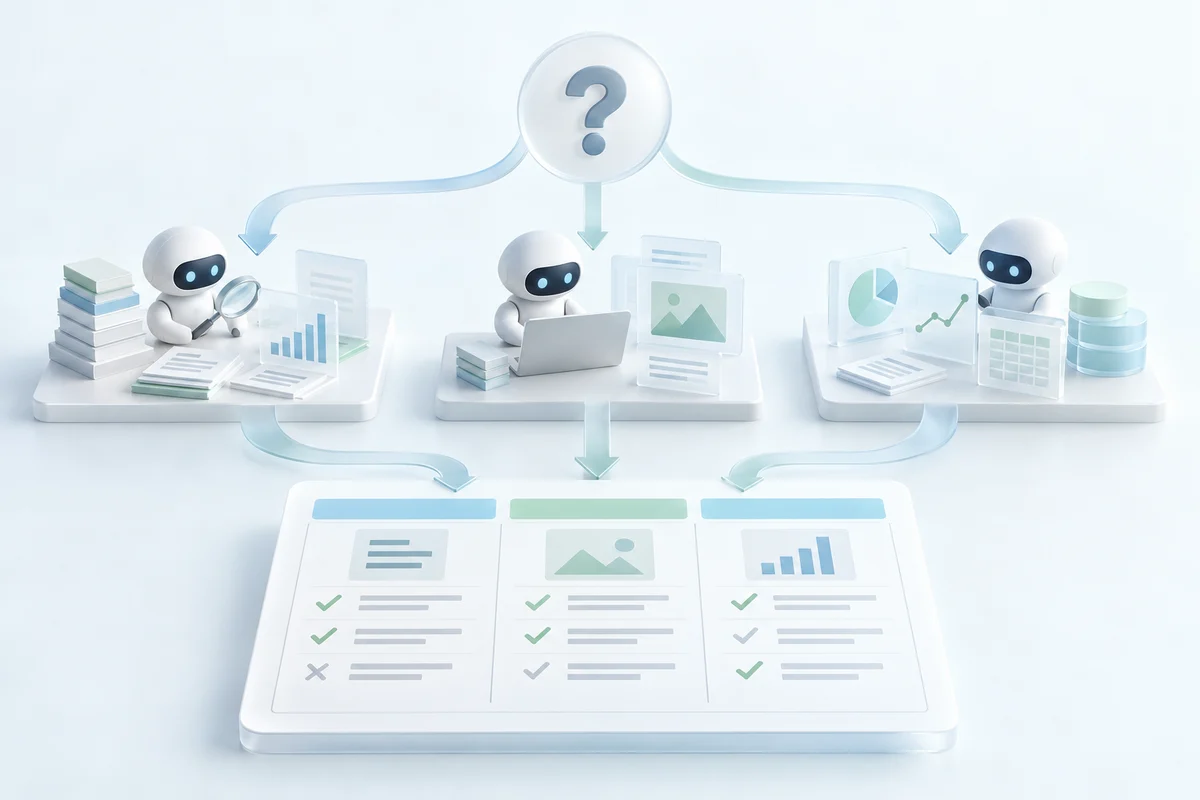
Three completed investigations do not make a completed comparison
A team asks AI to research three software products before choosing one. Separate agents can read the vendors' material concurrently. Their results arrive: one investigated the free tier, another the enterprise tier, and the third an older version. All report completion, yet a person must repeat the research to align the conditions. This hypothetical example distinguishes a shorter wait from earlier access to findings that support a decision.
A subagent receives a bounded task from a lead agent and investigates or acts within that scope. Using material published by OpenAI, Anthropic, Google, Microsoft, and AWS by March 30, 2026, this article examines where to divide work. It does not claim that every vendor adopted one architecture or rank their products by speed.
My judgment is that a division should specify more than a role such as “researcher”: define its inputs, how far it can proceed independently, and what it must return for the next decision. Adding agents has little value if a person must verify their findings from scratch. Start by enabling independent work while preserving the conditions and evidence required for synthesis.
Choosing a smaller model differs from running work concurrently
OpenAI's March 17 announcement of GPT-5.4 mini and nano describes a Codex configuration in which a larger model plans and synthesizes while mini subagents search code, review files, or process supporting documents in parallel. Nano is positioned for tasks such as classification and extraction, but the announcement makes it available through the API; mini is the model described for Codex delegation.
Two choices are involved: selecting a model for a task and executing several tasks concurrently. Smaller models can receive sequential assignments, and multiple agents can use the same model. Combining unit-price savings and parallel execution into one number obscures what actually improved.
For the hypothetical comparison, extracting product names and versions can use constrained inputs and a checkable return format. Resolving conflicting documents and selecting a product for a use case requires further exploration and judgment. A subordinate assignment is not necessarily easy. After narrowing its scope, check whether the assigned model can resolve the ambiguity that remains.
Keep dependent work behind the result it needs
Collecting material about three products can proceed independently once the use case and target versions are fixed. Synthesizing the comparison must wait for those findings, and checking the recommendation requires the resulting table. Splitting collection across three directions differs from starting collection, synthesis, and verification simultaneously, even though both arrangements have three parts.
Supply matching conditions
Align the use case, target version, features being compared, and research cutoff. Set these conditions before each investigator starts.
Delegate independent exploration
Find product material and investigate conflicts. Assign scopes that can progress without waiting for another product's conclusions.
Return findings with evidence
Return facts, URLs, relevant locations, and unverified fields. Do not turn a failed investigation into a claim that a feature does not exist.
Decide whether findings are comparable
Compare results with matching versions and availability conditions. Return gaps to their investigator; do not use unverified differences to justify a recommendation.
This is the article's hypothetical procedure, not a requirement to create four agents. Fetching three predetermined URLs may need only parallel tool calls. Delegating to a subagent becomes useful when it should discover a new issue in a document and decide to pursue another primary source.
In coding, diagnosis, a patch, and tests of that patch depend on earlier results. Independent module reviews may run concurrently, but separate edits to the same target need integration. Dividing work according to which result each participant must wait for makes handoffs easier to explain than dividing it by job-like role names.
Separate contexts without discarding evidence
Anthropic's Claude Agent SDK design article describes subagents with isolated context windows that return only relevant information to the orchestrator. Investigators can read long product documents without making the lead carry every investigation's history. Context management is a potential benefit to assess separately from parallel speed.
A short conclusion alone, however, may erase the conditions needed for comparison. “Search supported” does not reveal whether it is enterprise-only, requires an external connection, or was checked in the relevant version. I recommend making each comparison field traceable to its source. Entire documents need not be copied, but compression must preserve conditions that could change the conclusion.
In the opening example, each investigator would link the verified version and features to evidence and distinguish unverified fields from empty ones. The lead would synthesize only comparable fields. Agreement among three agents reading the same outdated document does not add three independent sources of corroboration.
Conversely, copying the lead's entire conversation and all documents into every assignment reduces the value of separate contexts. Supply the common purpose and constraints, and make other material accessible when needed. The goal is to limit inputs while retaining what decisions require, rather than minimizing sharing for its own sake.
Fixed ordering and choosing a specialist solve different problems
Google ADK's documentation as of March 30 describes sequential, parallel, and loop workflows whose orchestration does not consult a model at every step. A subagent can use a model internally while predefined rules control execution order. An established procedure need not have a coordinator rediscover its sequence each time.
The corresponding research code example saves three investigators' summaries in distinct fields and passes them to a merger after all investigators finish. Concurrent execution and sharing results are separate decisions. Its summary instructions do not by themselves meet this article's evidence requirements: correct ordering still requires a separate check of research accuracy.
Bedrock's March 2025 general availability announcement describes both a supervisor that decomposes and synthesizes work and a routing mode that sends simple requests directly to specialists. Complex requests still return to coordination in that mode. Checking one product and comparing three products can therefore call for different amounts of coordination. This example is my interpretation, not a measured cost saving from routing.
Fixed procedures can be combined with investigators that change their exploration according to findings. Compare who determines order, who chooses a specialist, and where results are stored. These questions make it easier to select mechanisms for a particular job than a list of vendor terminology does.
Preserve conversation continuity and execution progress separately
A Microsoft Agent Framework session example available on March 30 wraps a workflow containing multiple participants as one agent and includes conversation history in subsequent calls. It also serializes history into a form that can be stored and restored. This preserves internal delegation while allowing a user to continue a previous conversation.
Remembering the request differs from recording which investigations finished. The separate checkpoint example at that date distinguishes conversation history from execution-state records. Its storage is in memory; that alone does not demonstrate recovery after process termination. These code samples illustrate designs, not execution or failure-recovery tests performed for this article.
If one hypothetical investigator fails, retain the other two results, the unfinished assignment, and the comparison conditions. After retrying, identify which result was replaced. If the target version changes during the work, check whether the existing results still match it. Resuming successfully does not produce a valid comparison if results from different conditions are joined.
The lead's job goes beyond placing results side by side
Delegated research moves some reading to AI while leaving the lead with discrepancies to detect. A person making the final selection needs to see the evidence used and the conditions still unverified. Handing over three long completion reports makes that person reconstruct the comparison table.
Define what allows each investigator to stop and what it should return when material cannot be found. The lead can then identify gaps and narrow further assignments. Asking everyone to restart wastes the benefit of independent exploration. If an early result is used, indicate whether an unfinished investigation could change the recommendation.
Role names do not restrict permissions. Configure research assignments without unnecessary update operations. Return separate artifacts and identify who may incorporate them into shared files or send them externally. Delegation divides work; it does not automatically remove responsibility for the final decision.
Count total work alongside cheaper calls
Anthropic's June 2025 research-system report describes benefits from exploring independent directions and difficulties with heavily interdependent tasks. In its data, multi-agent systems used about 15 times the tokens of ordinary chats. The comparator is chats, not single-agent systems, and the figure is not a universal cost multiplier. Delegation cannot be assumed to reduce cost.
Even three concurrent investigations leave time for the last investigator, assignment preparation, synthesis, and follow-up research. Lower usage of a large model can be accompanied by more small-model calls and retries. Include the person's work to align conditions in the time required to obtain decision-ready findings.
Give single-agent and delegated configurations the same request, source material, and quality criteria. Report quality comparisons under a fixed total budget separately from comparisons of time and cost to meet a fixed quality target. Record model changes rather than attributing their effects solely to parallel execution. Repeat trials and include factual errors, missing fields, rejected findings, integration, and human corrections.
Divide work into scopes that support the next decision
A short specification check for one product may need only one agent or a fixed retrieval procedure. Independent exploration of three products, with findings traceable to original material, gives a reason to delegate. Its value lies in enabling a person to proceed from sufficiently deep research, rather than in the appearance of several AIs working at once.
Try one division first, aligning inputs, exploration scope, returned evidence, and responsibility for synthesis. Reconsider it if integration rework outweighs reduced waiting. Select models, contexts, ordering, and storage individually, retaining divisions that improve the work required to deliver usable findings. That is the approach to subagents proposed here.