Can a finding return to an ordinary code change?
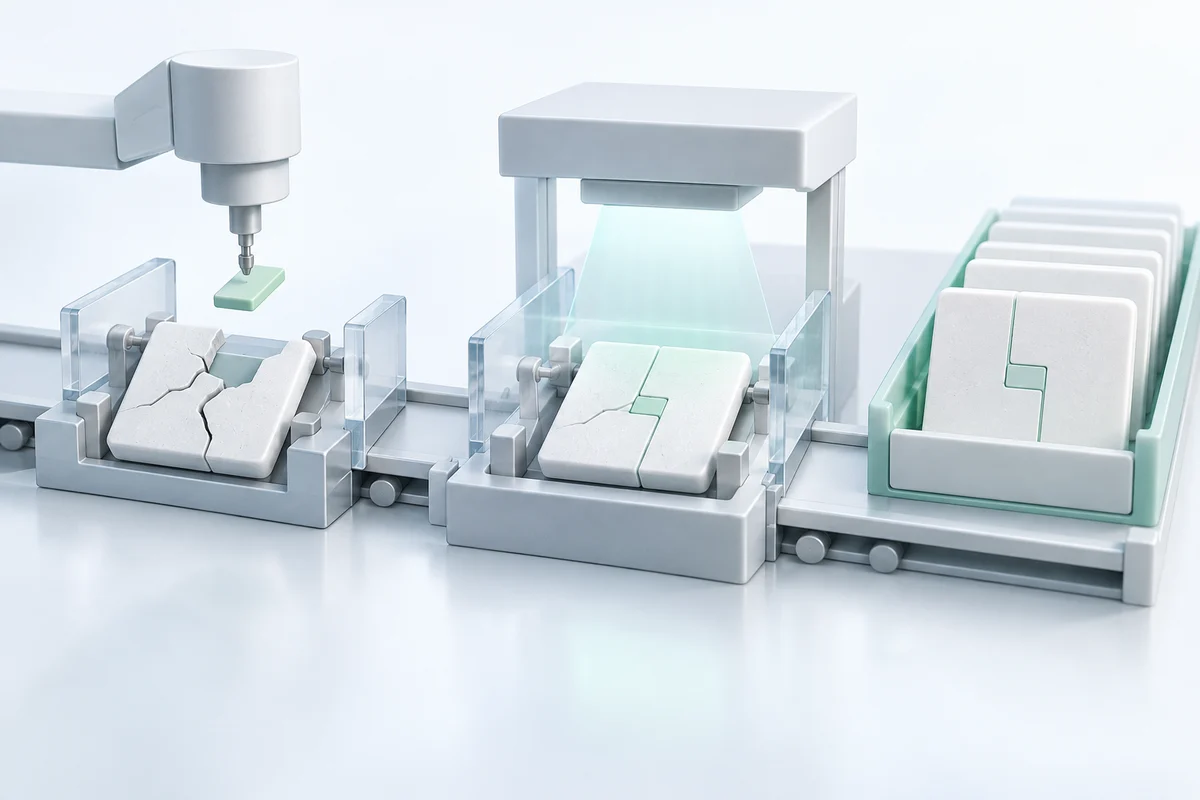
Announcements that AI has found vulnerabilities are becoming familiar. Development teams need to understand what happens next. Can they reproduce the report? Does the proposed patch remove the cause? Does it preserve legitimate behavior, and can a maintainer accept it through the normal review process? Detection improves a product when this sequence becomes manageable.
Google’s September 2026 infrastructure report describes one implementation. Google says it continuously scans changes across hundreds of millions of lines and prevents hundreds of vulnerabilities each month. Presubmit analysis combines localized threat models with structural triage, then sends proposed fixes into human review of the original change. Nightly integration scans also examine problems spanning multiple changes.
My emphasis is the connection between detection and acceptance. A change has an author, a purpose, and reviewers who can assess its intended behavior. Attaching security evidence to that change gives them a concrete decision. Google’s internal results do not establish the same precision or savings for another organization, but the structure explains how detection can become routine work.
Small reproduction tests helped Firefox engineers act
The receiving side matters. In Mozilla’s account of its collaboration with Anthropic, engineers contrast the usual burden of false-positive AI reports with submissions containing minimal test cases. Those tests enabled quick verification. Fixes landed ahead of Firefox 148, and the collaboration resulted in 22 CVEs, including 14 high-severity bugs.
This case separates AI-assisted discovery, engineering verification, repair, and release. The 22 CVEs demonstrate useful findings reaching fixes; they are not an accuracy rate over every candidate the system generated. Nor did a model independently complete the entire process. The maintainer received evidence that could be checked and converted into a product update.
A report’s value is not its length. A version, input, operation, and expected behavior let the recipient challenge its explanation in their own environment. A verifiable report can be easier to act on than a large list of plausible warnings. This is a condition for connecting model capability to maintenance work.
The crash location may differ from the repair location
Reproduction alone does not establish a correct patch. One XML example in Google DeepMind’s CodeMender announcement showed a heap buffer overflow whose cause was incorrect management of an XML-element stack. Editing around the crash could stop one input while leaving the underlying defect.
CodeMender’s described validation includes static and dynamic analysis, differential testing, fuzzing, SMT solvers, and model-based critique. Google reported 72 upstream security fixes during its first six months and said researchers reviewed every patch before submission. The architecture combines several ways to examine cause and behavior before human review.
Tool variety is not itself proof of correctness. A model critic can be wrong, and existing tests may omit important conditions. To interpret 72 accepted fixes, we would also need the number of attempts, rejected candidates, and changes maintainers made. Acceptance is valuable evidence, but it does not by itself explain verification cost or failure frequency.
GitHub makes the validation boundary visible
GitHub’s July public preview of agentic autofix brings this sequence into a common development environment. An assigned alert starts investigation of related files, patch generation, repeated CodeQL checks, and a draft pull request for review. Compared with a single suggested edit, it connects investigation and validation to submission.
The current documentation also states limits. Validation reruns CodeQL’s code-scanning query suite; it cannot confirm resolution of alerts from custom queries or the security-extended suite. Fix quality for third-party alerts is not guaranteed. Standard Copilot Autofix remains a separate approach that generates one suggestion for users to review and apply.
A pull request described as validated should therefore name what was checked: the analysis rerun, reproduction inputs rejected, and legitimate operations tested. An alert disappearing is an observation. The claim that every related vulnerability and regression is gone requires broader evidence. Making this distinction helps reviewers decide what additional work remains.
What a crash-only success criterion misses
The September PatchBench paper studies this problem for C/C++ repairs. Tests that only ask whether a supplied proof-of-concept input still crashes can reward symptom suppression; memorized historical patches can also distort evaluation. The researchers move vulnerabilities into different code contexts and check both security and semantic correctness.
Across 11 agents, including the top three AIxCC systems, PoC-only validation inflated measured solve rates by an average factor of 1.83. This is a result for that comparison, not a universal production error rate. It nevertheless demonstrates a measurable gap between stopping the original attack input and repairing the cause while preserving required behavior.
Consider a hypothetical patch that disables an entire feature to block a malicious input. It might pass the reproduction test while failing users who need that feature. The example illustrates why attack rejection and legitimate operation need separate checks. A better success criterion changes the target from removing a visible symptom to repairing the defect.
Discovery, repair, acceptance, and release have different counts
DARPA’s final AI Cyber Challenge results distinguish deliberately inserted vulnerabilities from real ones. Teams found 54 synthetic vulnerabilities and patched 43. Separately, they found 18 non-synthetic vulnerabilities and provided 11 patches. The latter findings were being disclosed to maintainers; the competition announcement does not establish that all repairs had shipped.
CyberGymE2E proposes evaluation spanning discovery, reproduction, and repair across 920 vulnerabilities from 139 open-source projects. Such work helps compare a continuous sequence of tasks. A benchmark using historical vulnerabilities still differs from current maintainer review and product release, both in its conditions and in who carries responsibility.
A problem was found
A suspicious location is identified. Reachability and reproduction still need checking.
A patch was validated
Attack reproduction and legitimate behavior were checked within a stated test scope.
A maintainer accepted it
The project incorporated the change. Human edits and review time also matter.
A release reached users
The repaired version was delivered. Delay after acceptance remains part of the process.
Measure the verification work as part of the benefit
I would begin with one alert class already handled by existing tools. Each AI proposal should carry a reproduction test, causal explanation, patch, and legitimate-behavior checks into the normal review location. Before automatic acceptance, establish whether these materials reduce verification time. Existing analysis and fuzzing can provide checks on the model’s judgment.
Keep false positives, failed reproductions, unsuccessful repairs, timeouts, and heavily rewritten proposals in the record. Compare time from verification to release, recurrence and regressions, and combined machine and human cost with the existing process. Finding one serious flaw can be highly valuable; whether a team can sustain that work every day requires another measurement.
Firefox’s acceptance case and Google’s development integration show concrete routes from AI discovery to repair. PatchBench and GitHub’s documented limits show why omitting validation scope exaggerates the result. I would judge practical AI defense by whether people can verify the evidence and deliver a repair that preserves required functionality, alongside the number of findings a model produces.